How to Train a Custom Object Detection Model for Your Robot
ContentsWhen You Actually Need a Custom Model
Pre-trained object detection models can recognize hundreds of common objects, but most robotics projects eventually need to recognize something specific that generic models don't cover: a particular tool, a custom game piece, a specific marker. This guide walks through the process of training a custom detection model and getting it running on your robot.
When You Actually Need a Custom Model
Before training anything, check whether you really need one. If your target is a common item (bottle, person, chair, common animals), an off-the-shelf pre-trained model will likely already detect it. Custom training makes sense when your object is unusual or specific (a particular product, a custom-built game piece, a specific tool), when you need to distinguish between visually similar variants, or when you need higher accuracy on your specific object than a general-purpose model provides.
Step 1: Collecting Images
This is the stage most beginners underestimate. A model is only as good as its training data:
- Variety matters more than quantity. A few hundred images from different angles, distances, and lighting conditions will outperform a thousand near-identical images.
- Match your deployment conditions. If the robot will operate indoors under artificial light, training on outdoor daylight photos will hurt performance. Take training images in the actual environment where the robot will run.
- Include negative examples — images without the object — so the model learns what the object isn't, not just what it is.
Use your robot's actual camera to capture training images rather than a phone or different camera, since image characteristics (resolution, field of view, color profile) affect model performance.
Step 2: Labeling Images
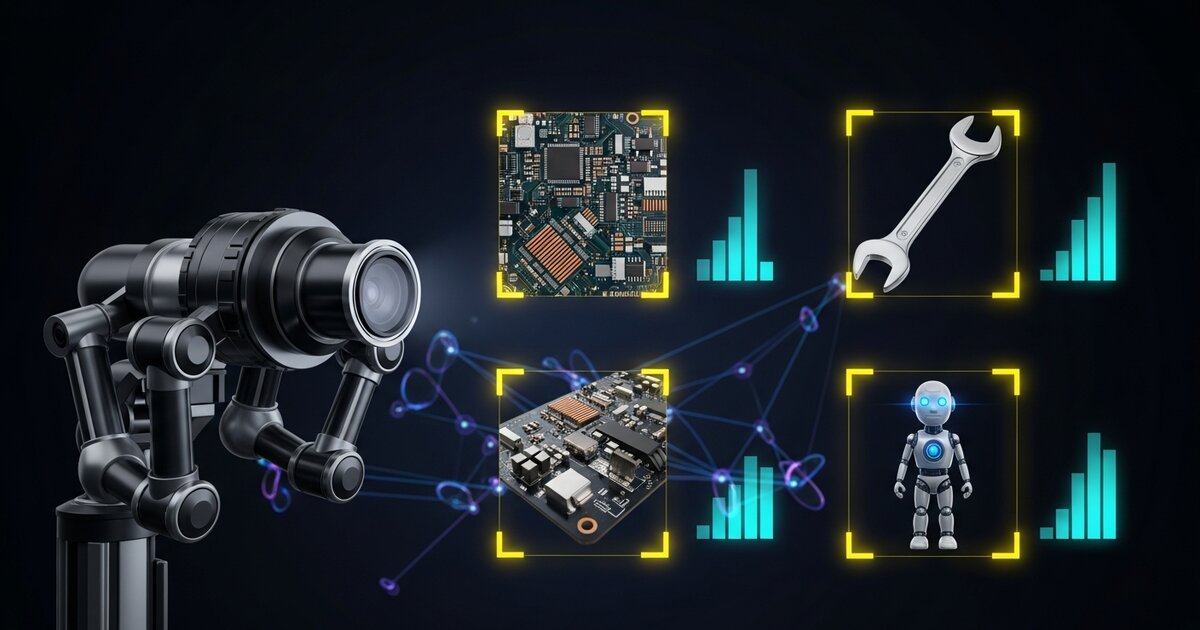
Labeling means drawing bounding boxes around your object in each image and assigning a class name. Several free and paid tools exist for this, most outputting in standard formats (YOLO or COCO) that training frameworks can read directly. Inconsistent labeling — varying tightness of boxes, sometimes including an object's shadow and sometimes not — introduces noise that makes training less effective. Establish a clear rule for borderline cases and apply it consistently.
Step 3: Training the Model
For hobbyist projects, training typically means fine-tuning an existing pre-trained model on your custom dataset, rather than training from scratch. Fine-tuning starts from a model that already understands general visual features (edges, shapes, textures) and adapts it to recognize your specific object — requiring far less data and compute than starting from nothing.
Popular lightweight architectures for edge deployment (the kind that run well on Jetson boards) include various YOLO variants, which balance accuracy and speed well for real-time robotics. Training is done on a desktop or cloud GPU, not on the robot — you train elsewhere, then deploy the trained result.
Step 4: Deploying to Your Robot
Once trained, optimize the model for your robot's hardware. On Jetson boards, this typically means converting with TensorRT, which optimizes the model's structure and precision for the specific GPU — often providing a significant speed boost over running the unoptimized model. After conversion, write an inference script that captures frames from the camera, runs the model, returns detected objects with bounding boxes and confidence scores, and feeds those results into your robot's decision-making logic (e.g., "if target object detected and centered, drive toward it").
Common Pitfalls
- Overfitting to your training environment: a model trained entirely in one room may fail completely in a different room. Vary training conditions as much as practical.
- Confidence threshold tuning: spend time tuning the threshold for your specific use case — too low gives false positives, too high misses real detections.
- Class imbalance: if 90% of training images contain the object and 10% don't, the model may be biased toward always predicting "object present." Balance your dataset.
Integrating with Navigation
A custom detection model becomes much more powerful combined with the navigation concepts from our SLAM Explained and ROS 2 for Beginners guides. For example: a robot that builds a map via SLAM, then uses object detection to locate a specific item within that map and navigate to it — combining "where am I" with "what am I looking at" into a single coherent system. Each individual piece is approachable on its own, even if combining all of them takes time.